Prompt Processing
Most advice about prompt engineering (Schulhoff et al. 2024) makes more sense once you understand what the model is actually looking at. Language Models, in Unit 1, explained how a model writes: one likely token at a time. This page is about what informs its output, specifically what happens between the moment you type into a chat assistant and the moment the model starts generating a reply. The discussion is intended to ground the later advice about prompting, verification, and choosing tools in a concrete understanding of the model’s behaviour.
The key idea is this: the model can only respond to the text currently in front of it, and it responds by extending patterns in that text. In Unit 1, you saw that LLMs can sound authoritative while being wrong, can be nudged by phrasing, and can be tricked into ignoring instructions. This page explains how the way you use them shapes all three.
Interface vs. Process
The conversational interface of chat assistants can make them seem like a knowledgeable conversation partner with a stable understanding of your question. The underlying process, however, is statistical text prediction based on the text currently in front of the model. This tension between the conversational interface and the underlying statistical process is exactly why these systems can be so useful, and also why they can drift, flatter, invent, and overstate claims.
The Model’s Actual Input
The model does not receive a question in the abstract. It receives a bundle of text assembled into a single input. Your visible message is only part of that bundle. Imagine you’ve uploaded some of Stevenson’s letters to a research tool such as Gemini Notebook, discussed them for a while, and now ask: Who is Colvin, and how does Stevenson talk about him? Here is what the model may actually receive:
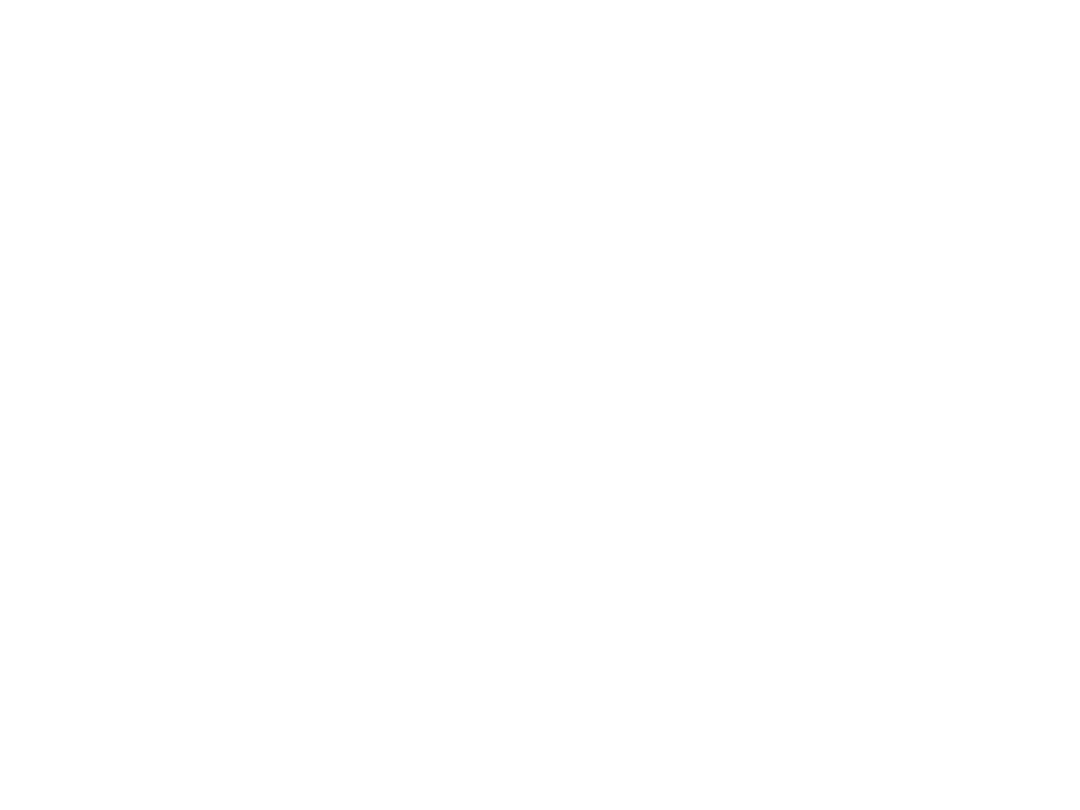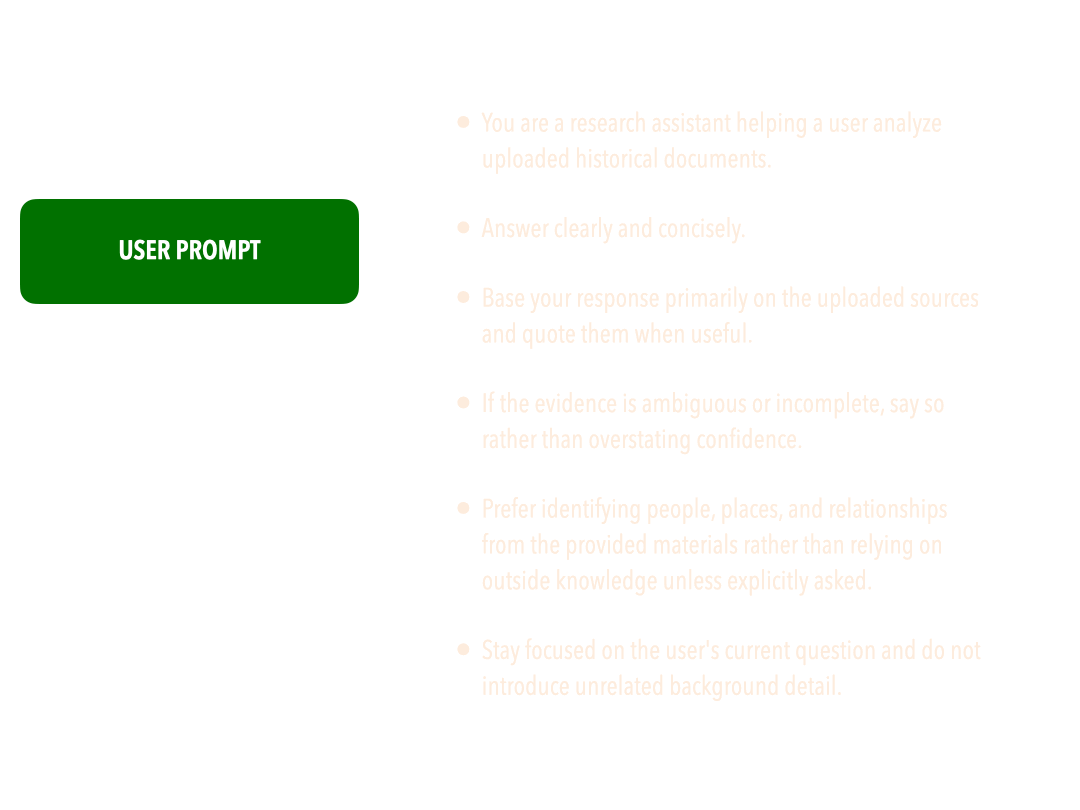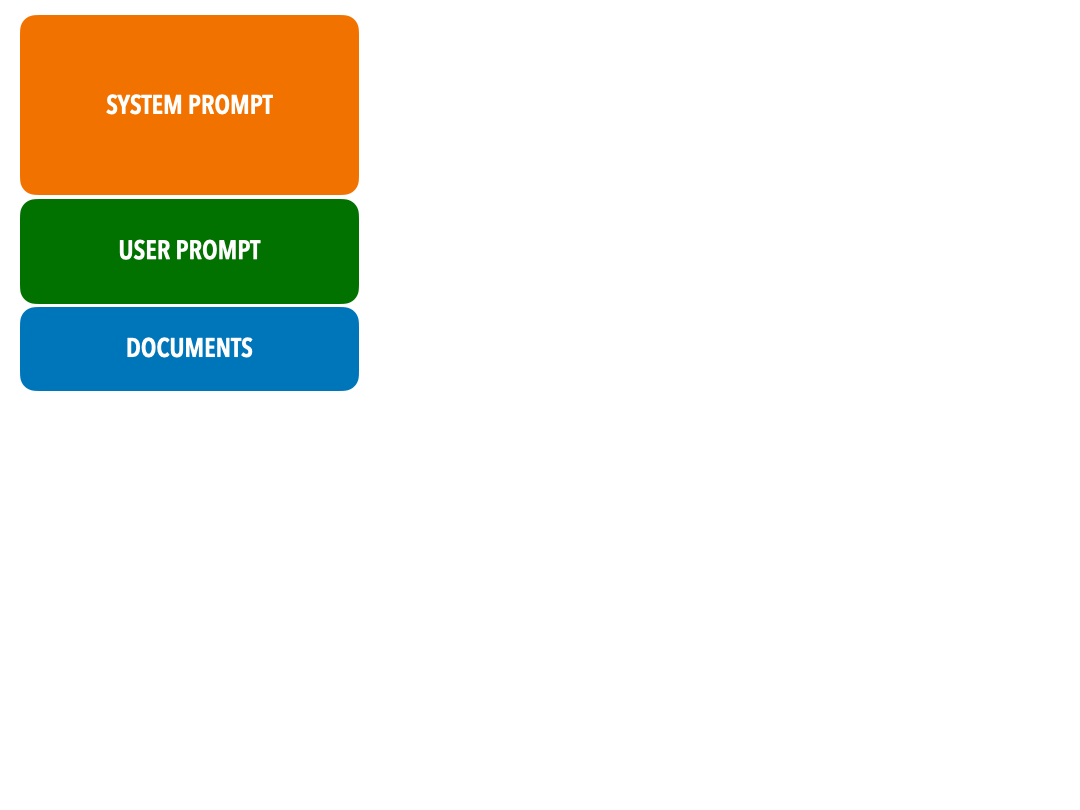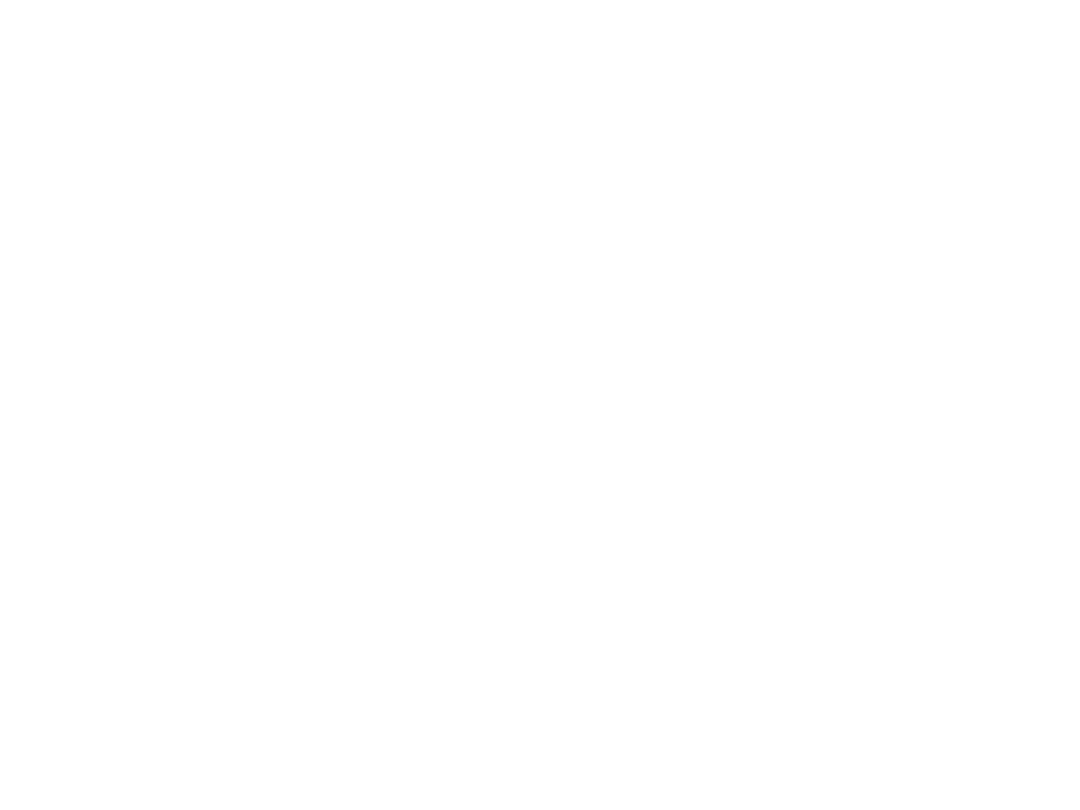
- Your prompt: the question you typed.
- The system prompt: hidden instructions from the application, which you usually don’t see (a few providers publish theirs). They typically say what role to play and how to behave: You are a research assistant helping a user analyze uploaded historical documents, Base your response primarily on the uploaded sources and quote them when useful, If the evidence is ambiguous or incomplete, say so.
- Documents: text from the sources you’ve uploaded, such as a letter to Stevenson’s mother that mentions that
Colvin is gone. - Chat history: the earlier turns of your conversation, your questions and the model’s answers, which the application sends again every time.
- Other context: anything else the application adds. Here, it’s passages that a search system picked out as relevant to your question: the heading
TO SIDNEY COLVIN, the salutationMY DEAR COLVIN, and a line from another letter,I have asked Colvin to send you a copy....
When a tool searches your documents (or the web) for passages related to your question, and adds them to the model’s input, it’s called retrieval-augmented generation (RAG). It’s how research tools usually handle sources too long to send in full, and probably part of how Gemini Notebook works (Google doesn’t say exactly): the model only sees the passages the search found, not the whole document. If the search misses something, so does the model (Lewis et al. 2020; Jurafsky and Martin 2026, chap. 11).
The model’s response is shaped by all of this together. If the retrieved passages are partial, if an earlier turn emphasized biography, or if the system prompt pushes for short answers, the response can change even though your visible question stays the same. This also explains several things you may have seen: why a model can refer back to something you said earlier, why a research tool can answer questions about your uploads, and why prompt injection works (competing instructions all end up in the same bundle of text, as you saw in Hack Merlin) (Greshake et al. 2023).
The model is not reading your intentions. It is responding to the package of text the application has assembled.
Context Windows
An LLM can only work with a limited amount of text at a time. That limit is called the context window.
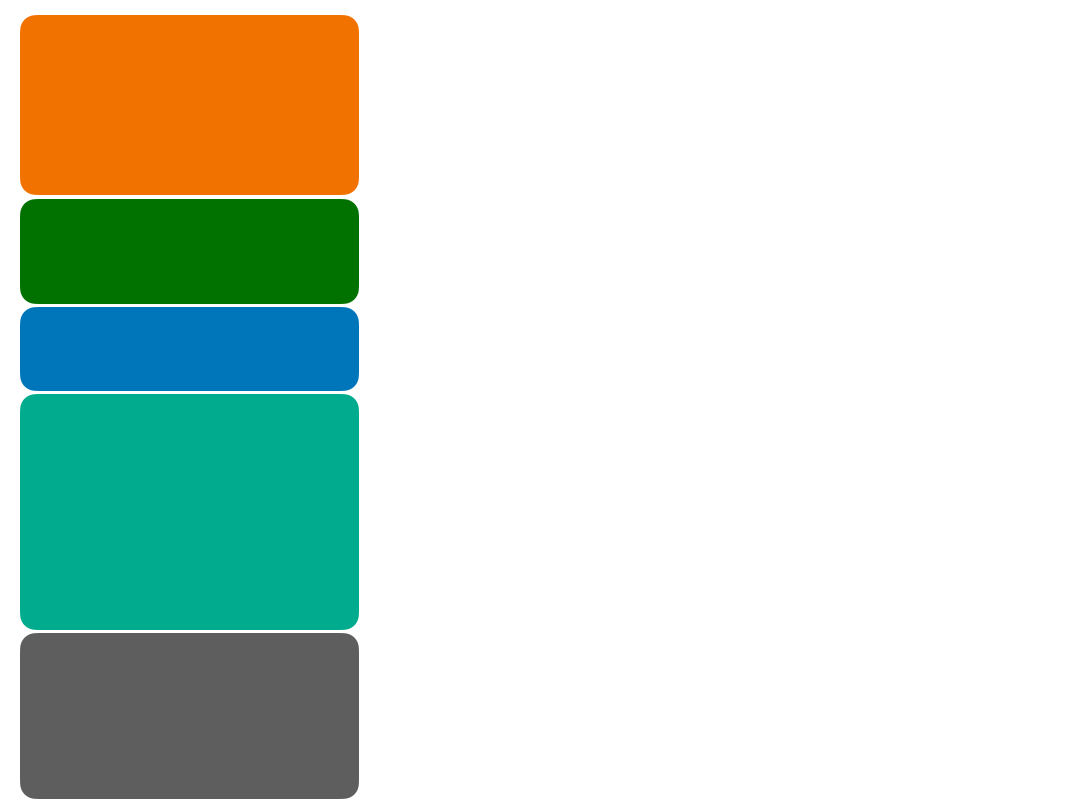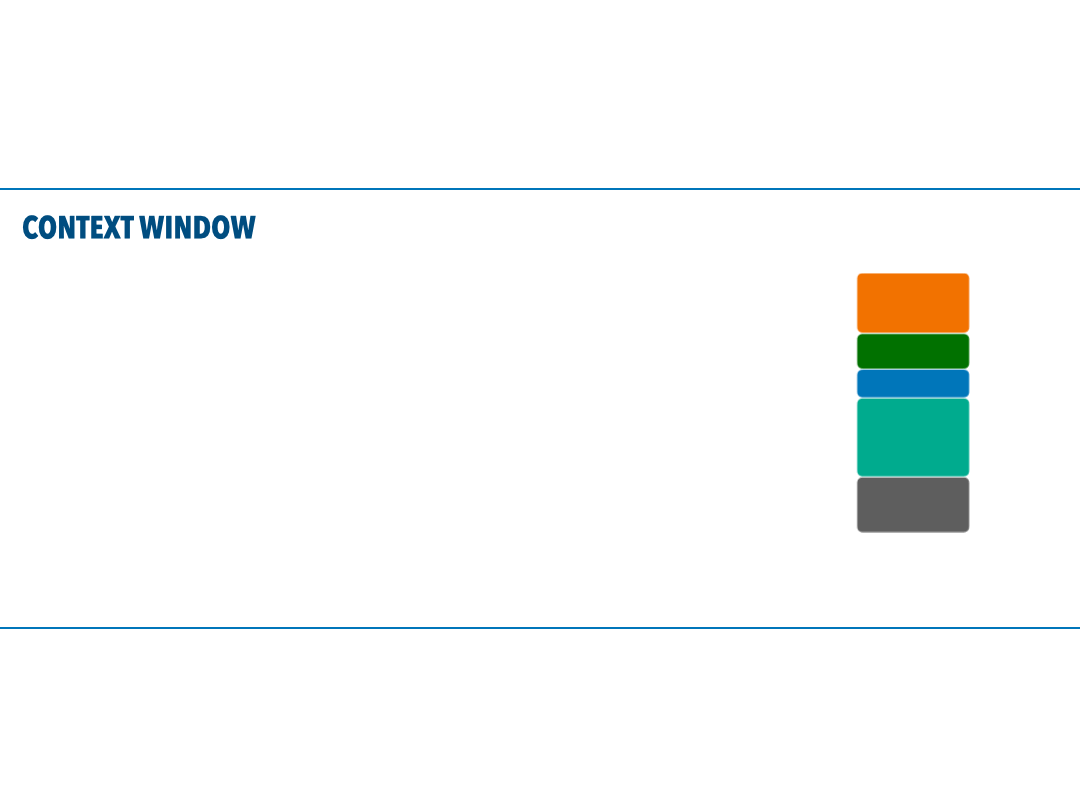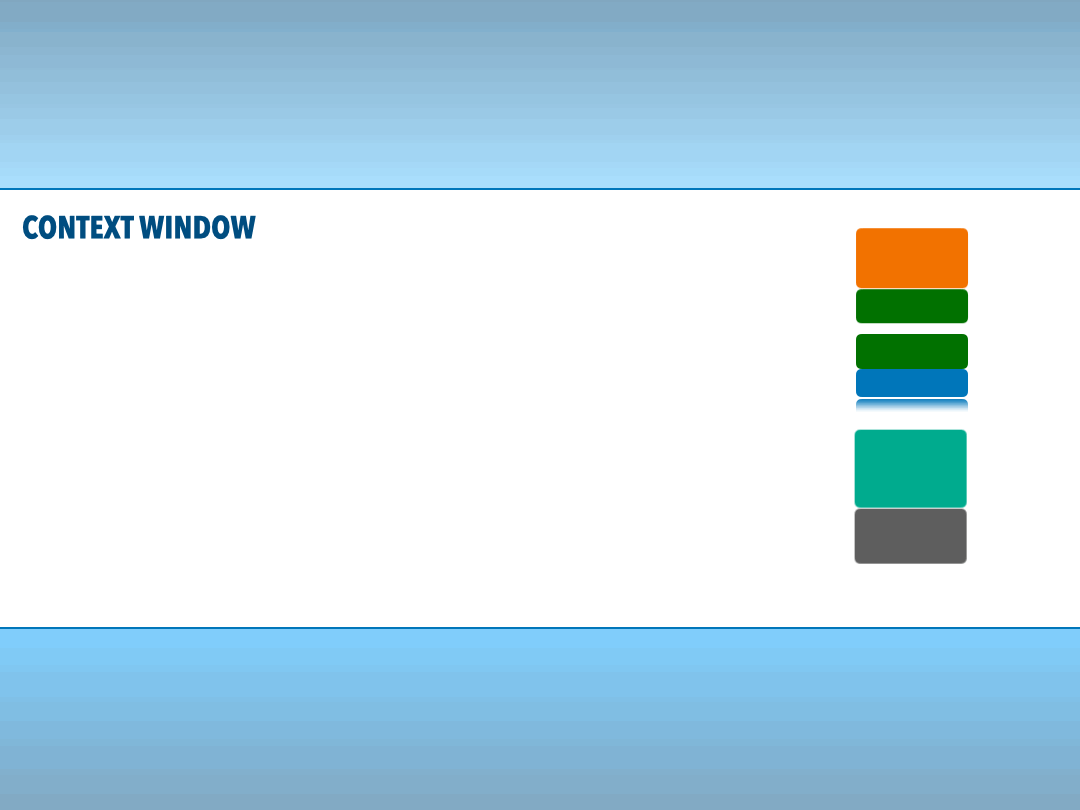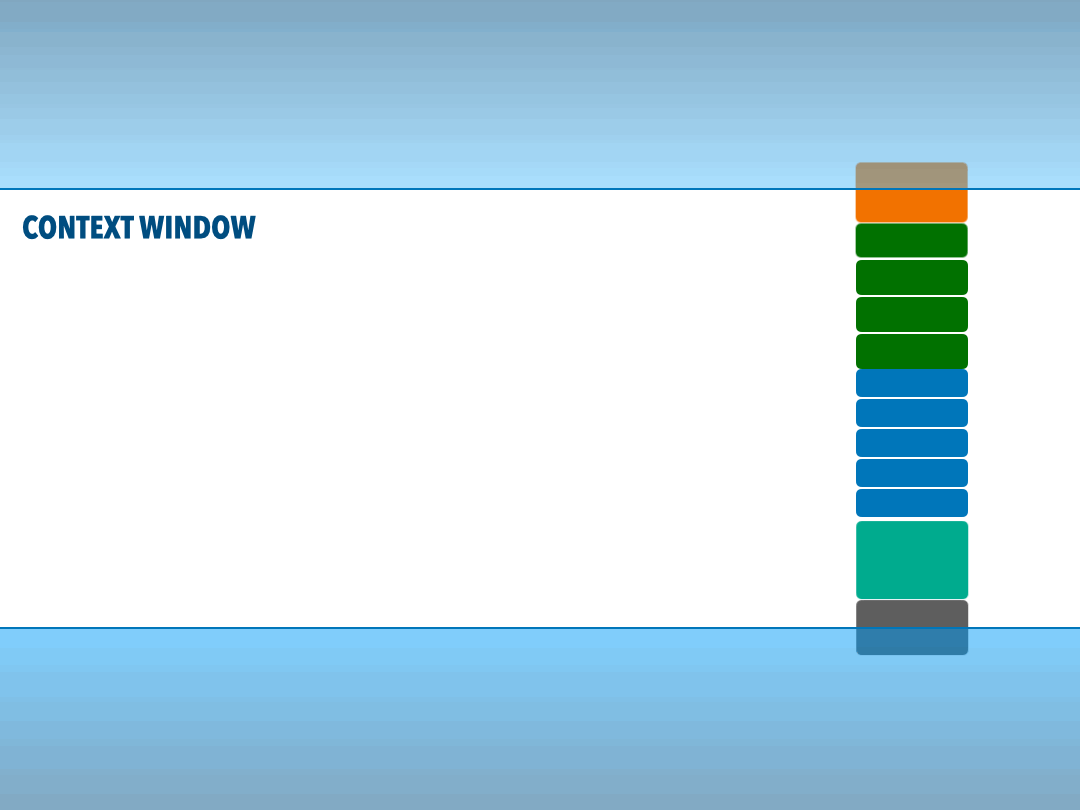
Everything in the bundle has to fit into the window: the system prompt, your prompt, the documents, the chat history, and any retrieved passages. As a conversation goes on, the bundle grows. Every new question and answer is added to the history, and every new upload adds documents, until it no longer fits. Then something has to give: the application drops or compresses parts of the input, often the oldest turns of the conversation, and the model never sees them.
- The window is shared space. If you paste in a long article, the article competes with everything else that has to fit.
- It is measured in tokens, not words or pages (see Language Models).
- Even inside the window, attention isn’t evenly spread. Information in the middle of a long input is often used less reliably than information at the start or the end—the lost in the middle problem (Liu et al. 2024).
This is one of the reasons long conversations degrade: constraints or corrections you gave early on may quietly stop being honoured. Tools often advertise very large context windows, but even so, assume that where material sits in the input, how prominent it is, and whether it has been compressed all affect the answer (Hsieh et al. 2024).
If you paste ten letters, ask three multi-part questions, and request a strict output format, the model is juggling all of that at once. A weak or partial answer may reflect overload, not just bad prompting. And if you work with long sources (whole books, archival collections, long interviews), you often can’t just feed everything in: material has to be split into chunks, or searched with RAG, and both introduce their own gaps.
Summaries deserve special attention. A model produces a summary by predicting what a likely summary looks like, not by reading and distilling the way a human would. Summaries can therefore be fluent but misleading: they tend to drop unusual or low-frequency details that happen to be important, and to reproduce common framings (Peters and Chin-Yee 2025).
Tokens and Messy Sources
Language Models showed how text is split into tokens, and how names, ALL-CAPS text, and old spellings break into fragments. For historical sources, this has practical consequences. Archival material often includes unusual capitalization, damaged text, inconsistent spelling, marginalia, and transcription artefacts. These are not cosmetic issues: they change how the model breaks up the input. A person who sees St. Jhn's may infer a damaged place name, a model sees an unusual sequence of fragments, and may behave much less predictably. Clean, consistent text in the prompt usually gets better answers.
Instructions as Strong Signals, Not Hard Rules
Instructions strongly influence the model, but they don’t constrain it the way a program constrains software. This is what the Hack Merlin activity demonstrated. LLMs are trained to respond helpfully to instructions (Ouyang et al. 2022; Jurafsky and Martin 2026, chap. 8), and products add their own instructions above yours. In practice, this creates something like a hierarchy: the application’s hidden directions, then your request, then quoted material or examples. But the hierarchy isn’t absolute, the way a security rule in traditional software is (Wallace et al. 2024). That is why models sometimes ignore part of an instruction, follow the wrong one, or get manipulated by cleverly framed prompts.
A spreadsheet formula, for example, follows exact rules, while an LLM follows learned patterns of what instruction-following usually looks like. Prompting is mostly the practice of reducing ambiguity and building better constraints inside a system that doesn’t obey constraints perfectly. Prompting Strategies turns this insight into practical advice.
Drift, Forgetting, and Self-Contradiction
Many frustrating LLM behaviours follow directly from context dependence and probabilistic generation.
- Recent or repeated text often has outsized influence (Zhao et al. 2021).
- Conflicting instructions can produce unstable behaviour.
- Small changes in the wording of the question can significantly alter the response (Sclar et al. 2024).
- There’s random choice involved in the selection of every token (sampling), so the same prompt can produce a different answer.
- The model may sound consistent even when its underlying judgement is unstable.
The model doesn’t keep a stable interpretation of your material stored somewhere off to the side. Its behaviour emerges from the conditions of the current input. A slightly different framing shifts which patterns are most prominent, and a good answer once is no guarantee of the same answer again.
A conversation with an LLM is not a stable analytical pipeline. It is an interaction whose output depends on the exact context of that moment. That’s fine for exploration, but a real problem for research that needs to be repeatable, a theme that runs through the rest of this unit and into Unit 3.
Exercise
Throughout this unit, you’ll work with one short letter: Stevenson’s letter to Sidney Colvin of August 1877, wikisource_vol1_ch3_letter14.txt. Read it first, it takes just a couple of minutes. Keep a document open to paste the model’s answers into as you go: you’ll need them in later steps.
- Open a new conversation in any chat assistant (ChatGPT, Claude, Gemini, or similar), paste in the letter, and ask: Summarize this letter, and list the people it mentions.
- In the same conversation, ask: Who is “Stephen”, and how do you know?
- Open a second new conversation. First ask: In everything that follows, focus only on places. Then paste the letter again, and repeat the question from step 1.
- What did the model add that isn’t in the letter? The letter says only
Stephen. A chat assistant will probably tell you this is Leslie Stephen, the editor of the Cornhill Magazine. That’s likely right, but it doesn’t come from the letter: it comes from the model’s training data, combined with the context clues (CORNHILL pages). Did it say so, or present it as if the letter stated it? - Did it list things that aren’t people?
Villonis Stevenson’s name for his own writing about the poet François Villon: in this letter, a story and an essay.CORNHILLandTEMPLE BARare magazines, though both are also places in London. - How did the second conversation differ? The letter and the question were the same, only the earlier turn was different. That earlier turn is part of the bundle the model receives, and it shapes the answer.
Key Takeaways
- The model only knows the text currently in its input: your message, plus hidden instructions, chat history, uploaded documents, and retrieved passages, and whatever it learned in training.
- Research tools often use RAG: the model sees only the passages a search found, not your whole document.
- The context window is limited. Long conversations and long sources get trimmed or compressed, and the model never sees what was dropped.
- Instructions help, but they don’t work like hard program rules.
- A conversation is not a stable pipeline: the same question can get a different answer.
If you want to read more, the following are a good place to start:
- Liu et al. (2024): a research paper, but its first figure shows the lost in the middle problem at a glance: how accuracy drops when the relevant passage sits in the middle of a long input.
- Kelly Hong, Anton Troynikov, and Jeff Huber, Context Rot (2025): a readable report, with charts, on how current models do worse as their input gets longer.
- Peters and Chin-Yee (2025): a study of how LLM summaries of scientific papers overstate their findings, by leaving out the details that limit them.